
AI Agents Design a CPU From Scratch, Claim 4.59x Better Efficiency in Simulation
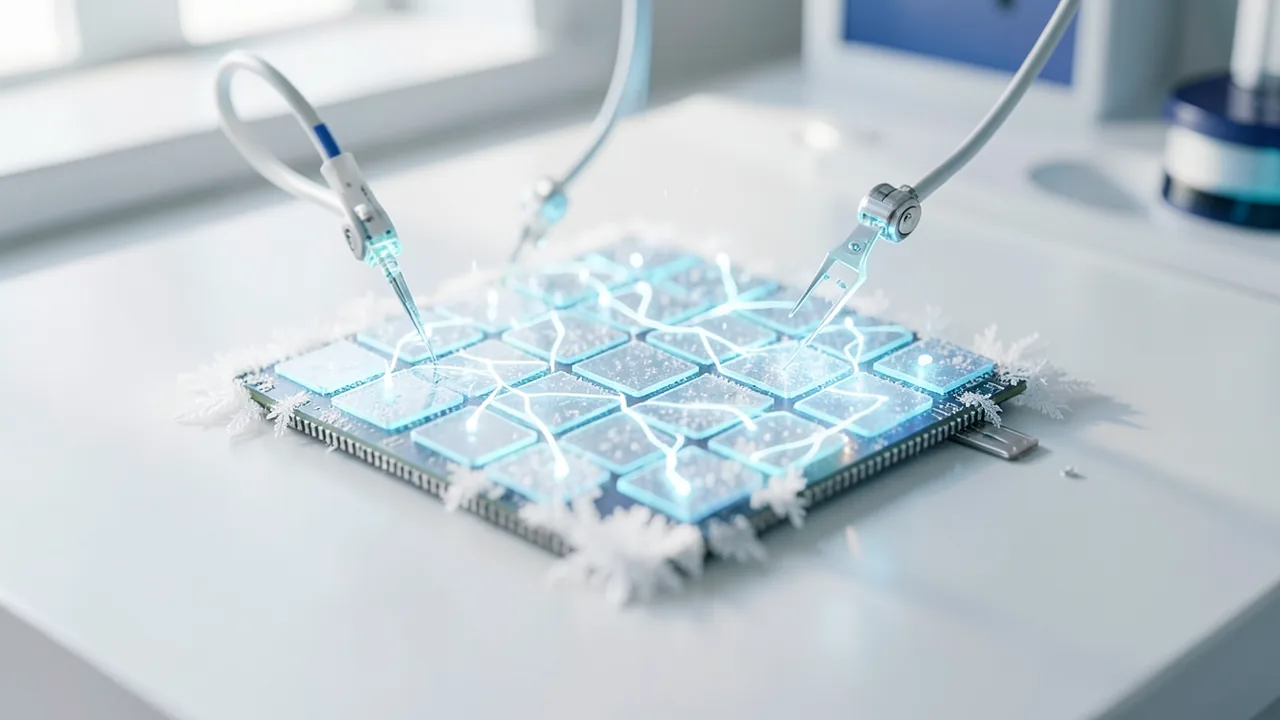
Startup Architect Labs had AI agents design a CPU architecture from the ground up, covering everything from the instruction set and circuit design to the finished chip layout. In the company's own simulations, Frostbite averages 4.59 times the performance per watt of a conventional CPU core of the same size. The chip hasn't actually been built yet.
What's going on
In mid-November 2026, Architect Labs unveiled a new processor architecture called Frostbite. What makes it unusual: according to the company, the CPU wasn't designed by human engineers. Swarms of AI agents designed and verified it, largely on their own. Their work covered the compiler (the program that turns source code into machine instructions), a brand-new instruction set (ISA, the "language" a processor understands), the circuit description (RTL) and the final manufacturing layout (GDS, the file a chip fab uses to produce the chip).
In an earlier project called Redwood, Architect Labs had already shown that its AI systems could implement and verify a given design for an AI accelerator. With Frostbite, the team set out to answer a bigger question: can AI discover a new hardware idea that clearly beats human designs? The company says yes. It claims Frostbite averages 4.59 times the performance per watt of a modern conventional CPU core of similar size. But every one of those numbers comes from simulation. No physical chip exists yet.
The idea behind it: interaction nets
Conventional programming languages hide which parts of a program depend on each other. Any piece of code can read and modify shared memory. That's why modern CPUs have to work hard at runtime to figure out which instructions they can safely execute in parallel. On top of that, single-core performance has barely improved since the early 2000s, so vendors pack lots of cores onto one chip, as with Intel Xeon, AMD Zen or NVIDIA Vera. For all those cores to "see" the same memory, you need deep cache hierarchies (fast intermediate memory) and coherence protocols, the rules that keep those caches in sync. All of that costs die area and power, and it scales poorly.
Frostbite is built on interaction nets, a model of computation that computer scientist Yves Lafont introduced in 1990. A program is a graph of nodes, and computing means rewriting pairs of connected nodes according to fixed rules. Each step only touches a small, local part of the graph. Because every node has exactly one "principal port", these active pairs never overlap. You can rewrite them in any order, or all at once, and the result stays the same. And since every value is used exactly once, there's no shared mutable memory for the hardware to protect.
Architect Labs uses the example of placing five queens on a 5×5 chessboard so that none of them can attack another. According to an analysis by xenospectrum, the net involves 3,183 rewrites, but the longest dependency chain is only 262 steps. In theory, that means about twelve steps can run at the same time on average. xenospectrum stresses, however, that this is an ideal upper bound, not the speedup you'd expect on four compute tiles.
Programs for Frostbite are written in Vine, a language with Rust-like syntax. It compiles to an intermediate representation called Ivy, which preserves the net structure.
How the AI designed the chip
Humans first chose the test programs. They covered a range of patterns: many independent subtasks, rounds of parallel work, long sequential chains, data-dependent branching and recursion. Each category had one set for optimization and a held-out set for final evaluation. FFT, radix sort and LU come from the well-known SPLASH-2 benchmark suite, but were scaled down to 1/64 of their original size. Later, five real-world workloads were added: a Kalman filter, principal component analysis (PCA), finite element analysis, an LU solve and LZ4 decompression.
The agents combed through the research literature, built Python models and produced a 141-page design document. It was scrapped after the first round of circuit generation because many of its estimates were physically unrealistic. As a replacement, Architect Labs developed its own formal specification language called ASL. Unlike prose documents, it can be checked by machine and translated into the Lean proof assistant, a tool for mathematically proving that something is correct. In the end, the specification ran to more than 800,000 lines of Lean code. The company says this single provable "source of truth" prevents many bugs, hallucinations and cases of reward hacking, where AI agents game their evaluation target instead of actually solving the task.
The system model written in ASL, called "Arcmodel", runs about 200 to 660 times faster than a simulation of the circuit, according to the company. At first, its power estimates were off from the real circuit by up to almost 250 percent. So an autonomous process calibrated the model against counters such as memory accesses and network messages until the error dropped below 5 percent. Swarms of agents then tried out changes in parallel. Over four search rounds and final ablation tests (experiments where you remove individual components to measure what they contribute), they tested 58 ideas and kept 37. Among them: fine-grained clock gating, which shuts off the clock signal to circuit blocks that aren't currently in use.
What the AI "invented": stealing work
Since Frostbite has no central scheduler, the agents came up with simple rules for each compute tile: finish your own work first. When you run out, take work from a neighbor. If there's nothing there either, go idle and save power. When a loop or branch splits into parallel pieces, the tile parks the rest of the computation in local storage, the "frame manager", pushes the new tasks onto a hardware queue and picks up the newest one itself. Once all partial results are back, the parked computation resumes automatically.
Architect Labs says no human specified this behavior. xenospectrum adds some context: work stealing itself is a concept that's been studied for decades, including in a 1999 paper by Blumofe and Leiserson. What's new, according to xenospectrum, is mainly the specific queues and circuits the AI used to implement it.
The numbers in detail
Frostbite was designed for a 7-nanometer process. It hit 800 MHz at synthesis and 500 MHz in the final layout. The comparison pits a "quad" of 2×2 tiles plus four L3 cache nodes (0.792 mm²) against a single core of an already-manufactured in-order CPU that can issue two instructions at once (0.895 mm²). The company won't say which CPU that is, citing "legal reasons".
- Performance per area: 8.77x on average
- Performance per watt, all 25 workloads: 4.59x (geometric mean)
- Only the 10 optimization workloads: 6.02x
- Only the 15 held-out workloads: 3.83x
xenospectrum read the held-out results off the charts in the announcement:
| Workload | Performance/watt vs. TCPU |
|---|---|
| Convolution | 23.12x |
| Longest common subsequence | 6.35x |
| k-d tree | 6.19x |
| Kalman filter | 5.87x |
| PCA | 5.31x |
| Huffman decoding | 4.93x |
| Finite element analysis | 4.50x |
| Radix sort | 3.96x |
| Random forest | 3.07x |
| LU solve | 2.46x |
| LZ4 decompression | 2.44x |
| emeans | 2.32x |
| Breadth-first search | 2.20x |
| Quicksort | 2.09x |
| Fibonacci | 1.15x |
The median is 3.96x. The inputs are small: Fibonacci uses n=20, for example, and radix sort 16,384 elements.
On energy, excluding clock distribution (which accounts for 49% on the reference CPU and 41% on Frostbite), the share spent on fetching, decoding and issuing instructions drops from 27 to 6 percent, and memory drops from 57 to 38 percent. In exchange, Frostbite spends 26 percent on its on-chip network and work distribution. According to xenospectrum, this breakdown is based on 20 workloads rather than 25.
What's next
Architect Labs plans an FPGA-based testbed (FPGAs are programmable chips) where anyone can run programs on Frostbite. The company also promises a first operating system, comparisons against larger multi-core and out-of-order CPUs on standard benchmarks such as SPEC and PARSEC, and a release of the RTL and instruction set.
Our take
Frostbite is a striking example of how far agentic AI has come in chip design: from idea to manufacturable layout, backed by formal proofs. The really exciting part is that a decades-old niche concept like interaction nets can suddenly be tested in practice. Outsider ideas like this were long considered too expensive and too risky to investigate seriously.
Still, caution is warranted. All the numbers are vendor claims from pre-fabrication simulations. The 5 percent accuracy refers to how well two design stages match each other, not to measured power draw on a real chip. The reference CPU is a fairly simple in-order core, and it isn't named. The tests are small, and the spread from 1.15x to 23x shows that the advantage depends heavily on the workload. Programs also have to be written in the experimental Vine language, so existing software won't just run on it. How well the architecture holds up against modern high-performance CPUs will only become clear once the promised comparisons arrive.
Sources
- Hacker News – AI architectlabs.com
- xenospectrum.com xenospectrum.com
Ask the AI assistant
Questions about this article, installation or background? Our assistant knows this page and runs on our own machine, not in someone else's cloud.
The Assistant is an AI (Gemma 4) and can make mistakes – please check important details against the source. Questions are used only to generate an answer and are deleted after one hour. Please don't enter any personal data.

Comments
What do you think? Already tried it? Write it here, no sign-up needed.
Comments are public. Links aren't allowed, and we delete abusive posts. You can delete your own comment at any time in this browser. Learn more in the Privacy Policy.