
Hugging Face now routes LLM requests through OpenRouter, and BYOK breaks
Hugging Face is swapping out its own router for Inference Providers in favor of OpenRouter's. When you call open language models through Hugging Face, every request now goes to a suitable provider automatically. If one goes down, the system tries the next. If you've been using your own API keys, though, you'll have to change your setup.
What's happening
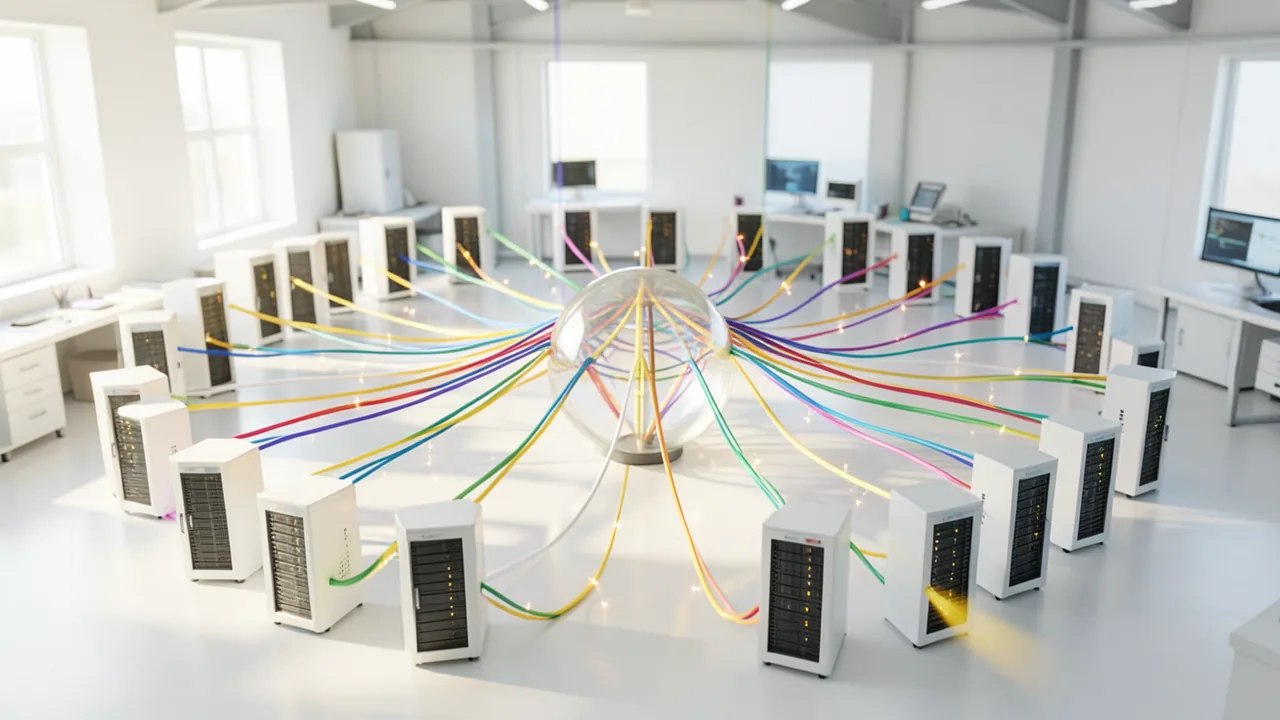
Hugging Face, the largest platform for freely downloadable AI models, is now partnering with OpenRouter. OpenRouter is a routing service: it accepts requests to AI models through a single unified interface and forwards them to one of many data center operators that host the model in question. According to an announcement on the Hugging Face blog on November 16, 2026, Hugging Face is replacing its own router in its Inference Providers service with OpenRouter's. Inference Providers lets you use models from the Hub via API without hosting them yourself.
In practice, any open-weight model on the Hub (meaning any model whose weights are freely available) can be called with your regular Hugging Face token, as long as some provider serves it. OpenRouter picks the right provider for each individual request. Hugging Face says you don't need to change your code. The switch only affects language models. Image, video and audio generation still run directly through Hugging Face, as before.
How the new routing works
OpenRouter says it serves more than 600 models from over 80 providers and processes more than 800 trillion tokens a month for over 10 million users. Tokens are the word and syllable fragments that language models use to process text, and they're also the unit you're billed in. With that much traffic flowing through, OpenRouter constantly measures how fast, cheap and reliable each provider is at any given moment.
OpenRouter recently rebuilt its routing logic. It used to be driven mainly by the lowest list price. Now each request goes to the provider with the best combination of price, speed and reliability. If a provider slows down or starts returning errors, the system routes traffic away from it until it recovers. If a request fails, the router retries it with the next-best provider in the same call. That's the key difference from before: Inference Providers used to pick one provider and simply pass its error message back to you when something went wrong.
OpenRouter cites its own measurements for the new logic (vendor figures):
| Metric | Change |
|---|---|
| Capacity errors | −46% |
| Time to first token | 16.9% faster |
| Throughput | +16.3% |
If you want more control, add a suffix to the model name. zai-org/GLM-5.3 uses the default mix, :fastest picks the provider with the highest throughput, :cheapest picks the cheapest one, and something like :novita sends requests exclusively to the provider Novita. The router is also cache-aware: a conversation sticks with the provider that already holds its prompt cache. That's a store of previously processed input that makes repeat requests faster and cheaper. If you want to pin this explicitly, send a fixed ID (UUID) per conversation in the X-HF-Session-Id header.
Works with popular tools
For every chat model, no matter which provider is behind it, the router speaks three widely used interfaces: OpenAI's Chat Completions and Responses APIs, plus Anthropic's Messages API. That means you can plug open models into coding assistants that were built for commercial models. Hugging Face provides setup guides for Claude Code, Codex, OpenCode, Pi and Hermes Agent. You can also copy the entire setup as a prompt and hand it to your own AI agent to work through.
The same token also gets you into other Hugging Face services: storage via Storage Buckets, compute via Jobs, and your own dedicated model instances via Inference Endpoints.
Pricing and more transparency
The pricing model doesn't change. You pay each provider's rate, billed through your Hugging Face invoice, and Hugging Face says it adds no markup. PRO users get $2 in credits every month, and Team and Enterprise organizations get $2 per seat.
Model pages now have two new tabs. Providers lists every provider OpenRouter can route the model to, each with input and output prices, speed and uptime over the last 24 hours. Metrics shows the best values among them for price, throughput, time to first token, context length (how much text the model can handle at once) and uptime. The usage dashboard shows how much each provider cost you. In your settings, you can block individual providers, for example for privacy reasons, and the router will never send anything there. Organizations get the same settings, and they apply to every request billed to the organization.
What breaks: your own API keys
There's one catch. Because language model requests now go through OpenRouter and are billed to your Hugging Face account, you can no longer add your own API keys for individual providers for these models. If you had a contract directly with a provider and used it through Hugging Face, you'll need to change your setup. You can still force a specific provider with a model-name suffix or switch off providers you don't want. Your own keys for image and video providers keep working.
As next steps, Hugging Face says you'll be able to connect your own OpenRouter account to Hugging Face and that more task types will run through OpenRouter in the future.
The numbers behind the open-model boom
The announcement also includes OpenRouter figures (as of October 2026) that show why the partnership makes sense for both sides. Open models' share of all tokens processed through OpenRouter rose from 26.8% in October 2025 to 71.7% at the end of September 2026, peaking at 77.5% in July. Over the same period, weekly volume for open models grew more than 60-fold, while closed models grew just under tenfold. The most-used model of the week on OpenRouter is an open one: DeepSeek V4.1 Flash 1017, with 59.2 trillion tokens.
Price is one reason. On average, open models cost about a quarter as much:
| Input (per 1M tokens) | Output (per 1M tokens) | |
|---|---|---|
| Open models | $0.28 | $1.62 |
| Closed models | $1.27 | $6.36 |
Hugging Face does admit that the best open models still trail the best proprietary ones on the hardest tests. On the Artificial Analysis Intelligence Index, a composite score built from several demanding benchmarks, the top open model, Kimi K3.1 Pro, scores 46 points. Claude Fable 5.2 scores 65. But a task run on Kimi costs only about a seventh as much ($3.68 versus $26.54). Hugging Face argues that this trade-off pays off for many applications.
Our take
The partnership combines two strengths. Hugging Face is where practically every open model gets published. OpenRouter's huge traffic volume gives it the measurement data to distribute requests intelligently. For developers, this makes using open models in production a lot more convenient: one token, familiar API formats, automatic retries on failure and no markup. Compatibility with OpenAI's and Anthropic's interfaces in particular makes it easier to drop a cheaper open model into a coding assistant.
There are downsides, though. Hugging Face is handing off part of its infrastructure and making itself dependent on an outside partner at a critical point. If you've been using your own provider keys, you lose that option. Whether the router really picks the "best" provider is something you can only check through the new transparency tabs. The 46% and roughly 17% improvements come from OpenRouter itself and haven't been independently verified. The same goes for the usage statistics, which come from the partner and support its business model. If you only want to trust your data to certain providers, restrict the provider list in your settings.
Sources
- Hugging Face Blog huggingface.co
- Merkliste: superpowerdaily.com superpowerdaily.com
- Google News (US) news.google.com
- Merkliste: maccus.fr maccus.fr
- Bing News (en-US) kingy.ai
- Google News (US) news.google.com
- The Decoder (EN) the-decoder.com
- The Decoder (DE) the-decoder.de
- Google News (US) news.google.com
- dev.to #ai dev.to
- dev.to #ai dev.to
Ask the AI assistant
Questions about this article, installation or background? Our assistant knows this page and runs on our own machine, not in someone else's cloud.
The Assistant is an AI (Gemma 4) and can make mistakes – please check important details against the source. Questions are used only to generate an answer and are deleted after one hour. Please don't enter any personal data.
Comments
What do you think? Already tried it? Write it here, no sign-up needed.
Comments are public. Links aren't allowed, and we delete abusive posts. You can delete your own comment at any time in this browser. Learn more in the Privacy Policy.