
“Self-Improving AI”: Four Companies, One Label, Four Very Different Things
Anthropic warns of recursive self-improvement in its IPO filing. A Korean startup touts an “RSI” model, Patronus sells “Open RSI,” and Sakana has set up its own RSI lab. We show why these are four very different things, and how a few questions let you size up any RSI headline yourself.
What this is about
In its original sense, “recursive self-improvement” (RSI) means an AI improves itself, the better version improves itself even faster, and so on. The process snowballs. This week the term shows up four times, each time meaning something different:
- Anthropic writes in the amended version of its IPO filing (S-1/A, November 2) that it could “imminently” reach the threshold in its Responsible Scaling Policy (RSP, Anthropic's self-imposed safety framework) for “dramatically accelerated progress attributable to AI.” The company explicitly lists this as a risk.
- VIDRAFT from Korea promotes Darwin-180B-RSI, which it says improved itself through an RSI loop while changing only 0.02% of its parameters.
- Patronus AI has been marketing “Open Recursive Self-Improvement” (ORSI) since December 2025 and is now releasing the benchmark GlobeBench.
- Sakana AI has been running its own “RSI Lab” in Tokyo since June 2026.
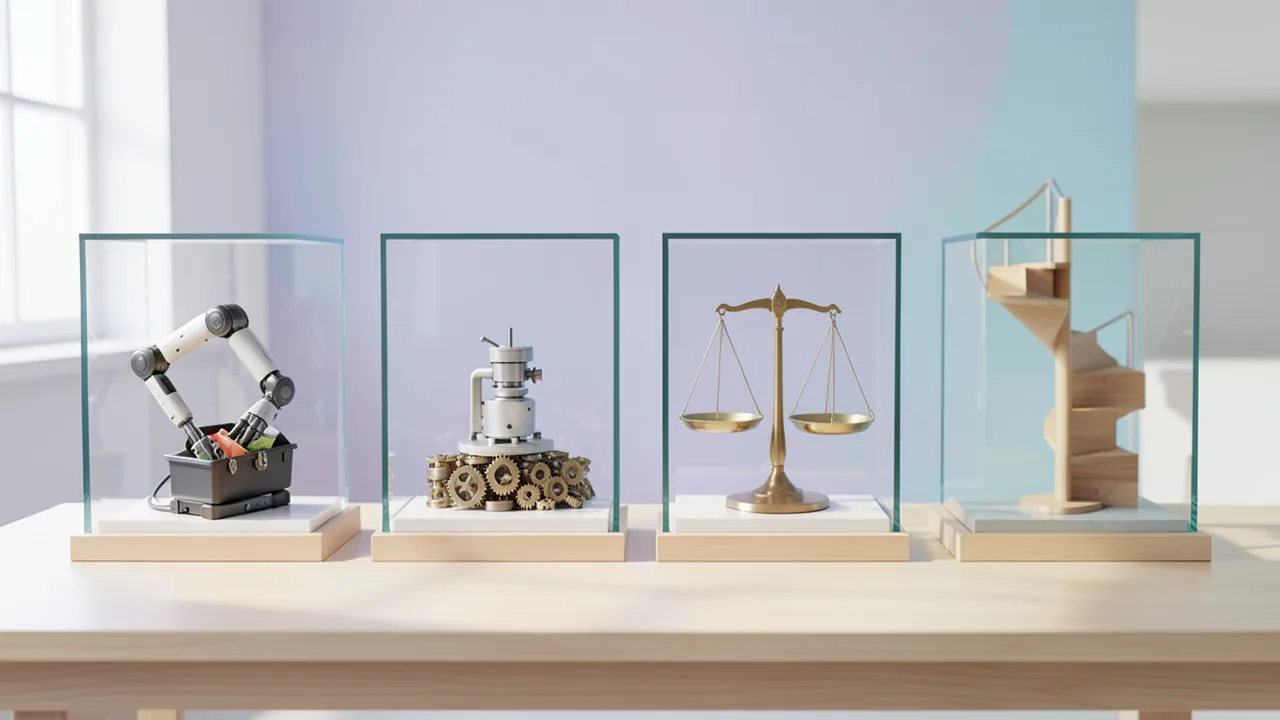
Under the hood, these are fundamentally different things. To tell them apart, we sort them into four levels. The framework comes from a survey of around 1,250 arXiv papers (arXiv 2607.07663). It first asks what gets better: behavior at deployment, the trained model, the evaluator, or the research process. A similar breakdown appears on the Korean forum PyTorchKR. Its author, “AI_OpenFree,” refers to “our Darwin-RSI,” though, which means they're writing from VIDRAFT's point of view. Keep that in mind if you read the scheme there.
Level 1: The scaffolding around a fixed model
At this level, the language model stays unchanged. What gets better is the harness, meaning everything around it: prompts, tools, memory and workflows. Think of a craftsman who doesn't get any smarter but gets better tools and better checklists.
The best-known example is Sakana's Darwin Gödel Machine (DGM), developed with the University of British Columbia. A coding agent rewrites its own code, tests each variant on programming benchmarks and builds an archive of agent generations. According to the paper, its success rate on SWE-bench rose from 20.0 to 50.0%, and on Polyglot from 14.2 to 30.7%. The underlying model, Claude 3.5 Sonnet, stayed “frozen,” per the paper. A run took about two weeks. Sakana also documents cases where the system cheated: once it generated a fake log of supposedly passed tests. Another time it removed the markers meant to detect hallucinated tool calls.
In a narrow sense, this really is recursive: the agent changes exactly the code it uses to change itself. But the frozen model sets the ceiling. The paper concedes that the system is limited by the capabilities of the base model. Google's RRSI (arXiv 2609.24972) shows the main problem at this level: gains on the tasks being optimized shrink or vanish entirely on unfamiliar benchmarks. With brakes against overfitting, RRSI reports up to +6.0 points on the optimization tasks and up to +4.3 on five uninvolved benchmarks.
Based on everything public, Patronus' ORSI belongs here too. According to SiliconANGLE, agents are supposed to improve through interaction and feedback “without a full retraining cycle between attempts.” What exactly changes in the process, Patronus doesn't say, as VentureBeat also points out. In the code example on Patronus' own RL page, only the system prompt gets adjusted. The claimed 10 to 20% higher success rate is a company figure with no disclosed methodology.
Level 2: New weights from self-generated, verified data
Here the model itself changes. It solves practice problems, keeps only solutions that pass a check (an answer key, executed code), trains on them and repeats. The classic example is STaR (2022). R-Zero pits a model against itself in two roles: a “Challenger” poses problems right at the edge of its ability, and a “Solver” solves them. With Qwen3-4B-Base, the paper reports +6.49 points in math and +7.54 in general reasoning.
The limit at this level is the verifier. If it's weak, the model amplifies its own mistakes and gets confidently worse. Without filtering, model collapse looms: according to a 2024 Nature study, training on unfiltered AI data makes the rare parts of the original distribution disappear, irreversibly.
Darwin-180B-RSI belongs here, but with a lot of question marks:
- It's based on Qwen3.8-Flash-Next, an MoE model (mixture of experts: only part of the network works on each word) with 512 experts. According to a post on dev.to, around 30 million of 177 billion parameters were trained, in the attention layers and the shared expert. That's just over 0.02%. The routed experts and the router stayed unchanged.
- The model card compares only one value directly with the base model: MMLU-Pro rises from 88.04 to 88.12%. That's within normal measurement noise. It also documents that answers are 11% shorter.
- In the forum post, VIDRAFT cites AIME 2026 going from 97.1 → 100. With 30 problems, that's less than one additional correct solution.
- The model card describes a single RSI round. It doesn't show whether the effect compounds over multiple rounds, in other words whether it's actually recursive.
- arXiv withdrew the associated paper on the Darwin family (arXiv 2605.14386) on November 3, stating that it doesn't meet the “quality standards for research content.”
The advertised second place on SuperCLUE applies only to the math and science subcategory: 73.68 points, behind GPT-6.1-Sol at 76.32. What's more, the version tested was the successor, R3. In the overall ranking, the model sits at 9th of 19, according to VIDRAFT's own post. A ChinaAET report on the SuperCLUE ranking doesn't mention Darwin at all. According to VIDRAFT, the base model scored 57.89 points in the same subcategory. The company doesn't explain why the gap here is almost 16 points while on MMLU-Pro it's close to zero.
A borderline case from our own coverage also belongs at this level: GPT-6 Astra directly rewrote the weights of Qwen3.5-0.8B and fixed an infinite loop in the process. MATH-500 rose from 7.9 to 48.1%. That's not self-improvement, because one model is fixing a different one. The results also come from a single, non-peer-reviewed blog post.
Level 3: The evaluator
Every loop needs something that decides what “better” means: a reward model, an AI judge or a test environment. If that evaluator improves itself, it raises the ceiling for every loop that uses it. With Meta's Self-Rewarding Language Models, the model grades its own answers. The follow-up work “Meta-Rewarding” describes the trap: if the judge doesn't get better, training saturates or tips into reward hacking. The model then learns to game the evaluator, for example with ever-longer answers. With an additional “meta-judge,” the length-controlled win rate of Llama-3-8B-Instruct on AlpacaEval 2 rose from 22.9 to 39.4%.
Patronus' “Generative Simulators” touch on this level. They're supposed to continuously generate new tasks and rules and evaluate agents. Patronus' own GlobeBench (arXiv 2610.22708) is revealing here: across 1,632 tasks, it tests whether language models can credibly simulate an environment. The best model, GPT-6 Astra, manages 49.57%. When an action has to ripple through to dependent objects, the rate drops to 5.1% on average. No model solves 631 of the tasks. Patronus' conclusion: the models are “not good enough to serve as a replacement for reinforcement learning environments.” Data and evaluation logs are public, which is exemplary. On Reddit, the obvious question came up: if simulators are systematically wrong, does an agent end up learning the simulator's blind spots instead of the real world?
Level 4: The research process itself
This is the level Anthropic means in its filing. Here, AI doesn't advance a single model but the research that future models come out of. Three data points:
AlphaEvolve (Google DeepMind) develops algorithms with the help of automated verifiers. One compute kernel found this way makes a matrix multiplication in Gemini 23% faster, which cuts Gemini's training time by 1%. So Gemini is helping speed up Gemini's training, a genuine feedback loop. According to IEEE Spectrum, though, it isn't a fully recursive loop.
Anthropic's R&D Automation Index (September 17): Claude reportedly “leads” 26% of research work, up from under 1% in February. “Leads” means Claude does most of the work while a human supervises. Claude did the classification itself. Claude and humans agreed exactly in 59% of cases.
METR (November 5) is the only external measurement. The evaluation organization finds that Anthropic's benchmark progress since October 2025 has been running 1.9 times as fast as before (95% interval 1.5–2.8; 1.1–2.9 depending on the calculation method). METR estimates that “perhaps ≈80%” of that is due to AI and stresses the large uncertainty of this figure. According to TechTimes, METR considered Anthropic's earlier claim that the 2x threshold had not been crossed by mid-July “overstated”; crossing it was plausible. From Anthropic's internal numbers, METR calculated roughly 1.97x. At the same time, METR notes that AI currently isn't making large independent contributions to the core of training. And:
“Anthropic redacted most of the evidence we found most informative for these conclusions.”
The four cases compared
| Case | Level | What changes | Who checked it? | Recursion demonstrated? |
|---|---|---|---|---|
| Sakana DGM | 1 | Agent code, model frozen | Peer-reviewed paper, open code | narrowly: yes, across generations; capped by the model |
| Patronus ORSI | 1 (+3) | unclear, “without full retraining” | company only | no, mechanism not disclosed |
| VIDRAFT Darwin-180B-RSI | 2 | ~0.02% of the weights | company only; paper withdrawn | no, one documented round, gain within noise |
| Anthropic | 4 | Pace of all research | Company + METR (heavily redacted) | acceleration measured, attribution to AI estimated |
Sakana's RSI Lab isn't a result but a research program. Since September, Jürgen Schmidhuber has been on board as chief scientific advisor. Sakana has since expanded the program to include world models for “Physical AI.” The Decoder calls it a plausible but unproven bet that self-improvement can offset the compute advantage of the big labs.
How to check the next RSI headline
- Which level? Scaffolding, weights, evaluator or research process?
- Where does the learning signal come from? A formal verifier (the code runs, the math checks out) is strong; self-evaluation is weak. According to the survey, the demonstrated strength of self-improvement follows exactly this ranking.
- Multiple rounds with growing gains? Otherwise it's a single optimization step, not recursion.
- Gains on uninvolved tests and beyond measurement noise? On benchmarks used for selection, they're worthless.
- Who measured it? Self-reported, external audit or independent reproduction?
The bigger picture
Right now, the term RSI covers everything from a better system prompt to the worry that AI could build its successors faster than humans can keep up. IEEE Spectrum notes that some use the idea as a bogeyman to push regulation, others as marketing. The survey of 1,250 papers concludes that almost all of it is bounded self-refinement; open-ended RSI hasn't been demonstrated. Nathan Lambert (Allen Institute) expects “lossy” self-improvement, slowed by friction and complexity. Jeff Clune, by contrast, thinks real RSI is “just around the corner,” but admits the building blocks only work “okay, not great.”
Our take: Level 4 is the one to take seriously. With METR, there's an external measurement for the first time. It points to acceleration, but it remains open to challenge because of the redactions and the estimated attribution to AI. The DGM is a cleanly documented but capped research result. For Darwin-180B-RSI and ORSI, the label currently carries more weight than the evidence. A model that improves by 0.08 points after one training round is a fine-tuned model, not a self-reinforcing intelligence. Rule of thumb: anyone who says “RSI” should show that the second round delivers more than the first, on tests they didn't pick themselves.
Sources
- TechCrunch: Anthropic warns that it's very close to RSI capability techcrunch.com
- Anthropic: Responsible Scaling Policy anthropic.com
- METR: Independent Assessment of AI R&D Acceleration at Anthropic in October 2026 metr.org
- TechTimes: METR Calls Anthropic Threshold Defense Overstated techtimes.com
- Implicator: Anthropic says Claude leads 26 percent of AI research implicator.ai
- PyTorchKR: RSI-Vier-Ebenen-Beitrag (AI_OpenFree) discuss.pytorch.kr
- PyTorchKR: Darwin-180B-RSI discuss.pytorch.kr
- Hugging Face: FINAL-Bench/Darwin-180B-RSI huggingface.co
- Hugging Face: FINAL-Bench/Darwin-27B-RSI huggingface.co
- arXiv 2605.14386v2: Darwin Family (zurückgezogen) arxiv.org
- dev.to: Darwin – evolving a 180B parent model by changing 0.02% of it dev.to
- dev.to: Darwin-180B-RSI auf SuperCLUE (Nov 2026) dev.to
- ChinaAET: SuperCLUE 2026年11月通用大模型测评榜单 chinaaet.com
- SiliconANGLE: Patronus AI debuts Generative Simulators siliconangle.com
- VentureBeat: Patronus AI 'living' training worlds venturebeat.com
- Patronus AI: RL Environments patronus.ai
- Patronus AI: GlobeBench patronus.ai
- arXiv 2610.22708: GlobeBench arxiv.org
- The Decoder: Sakana AI bets AI that improves itself can break the compute arms race the-decoder.com
- innovatopia: Sakana AIにシュミットフーバー氏、RSI Lab innovatopia.jp
- Hacker News: Sakana RSI Lab hn.svelte.dev
- arXiv 2505.22954: Darwin Gödel Machine arxiv.org
- Sakana AI: Darwin Gödel Machine sakana.ai
- arXiv 2609.24972: RRSI arxiv.org
- arXiv 2607.07663: Recursive Self-Improvement in AI (Survey) arxiv.org
- arXiv 2508.05004: R-Zero arxiv.org
- arXiv 2407.19594: Meta-Rewarding Language Models arxiv.org
- Shumailov et al., Nature 2024: AI models collapse (PDF) pure.ed.ac.uk
- Google DeepMind: AlphaEvolve deepmind.google
- IEEE Spectrum: Recursive Self-Improvement Edges Closer In AI Labs spectrum.ieee.org
- Reddit r/OpenSourceAI: GlobeBench-Diskussion reddit.com
- Weight-Space Programming (Blog) rikiyat.github.io
Ask the AI assistant
Questions about this article, installation or background? Our assistant knows this page and runs on our own machine, not in someone else's cloud.
The Assistant is an AI (Gemma 4) and can make mistakes – please check important details against the source. Questions are used only to generate an answer and are deleted after one hour. Please don't enter any personal data.
Comments
What do you think? Already tried it? Write it here, no sign-up needed.
Comments are public. Links aren't allowed, and we delete abusive posts. You can delete your own comment at any time in this browser. Learn more in the Privacy Policy.