
Study: Elaborate harnesses make coding agents costlier, not better
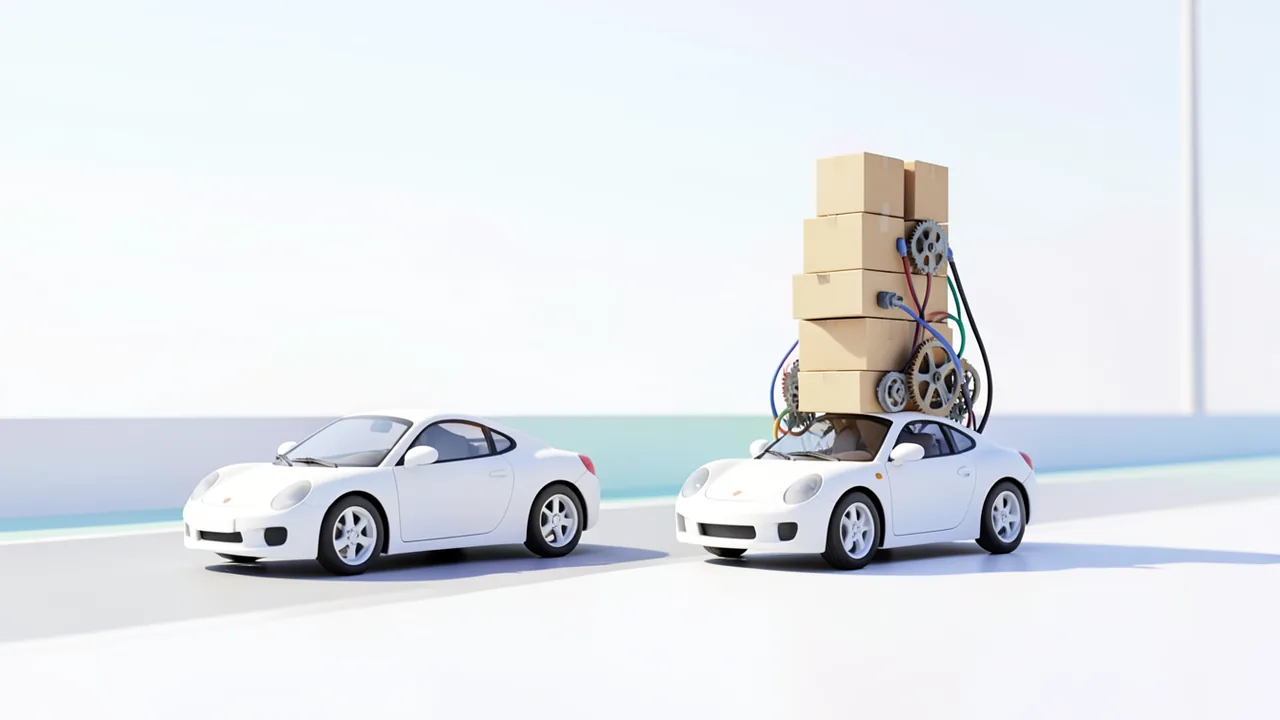
Two researchers at Shandong University measured how much a coding agent's wrapper (the "harness") adds when the model stays the same. The result: switching harnesses shifts the success rate barely more than a second run does, but costs can triple.
What this is about
A coding agent consists of a language model and a harness. That means the system prompt (the model's basic instructions), tools and context management that turn a chat model into something that can work in a code repository. New harnesses appear every day, vendors advertise higher success rates, and leaderboards mix them freely.
Two researchers at Shandong University (Liu and Han) used a preprint to measure how much the harness really matters when the model is held fixed. The title gives away the result: "What does a harness buy? Mostly tokens."
Earlier comparisons measured chance, too
Previous studies report differences of more than 20 points between harnesses. According to the authors, such figures almost always come from a single run. Even plain reruns of the same configuration vary by up to six points on SWE-bench Verified (a benchmark of real programming tasks from open-source projects). Zhipu AI, for example, advertises its harness with a 2.4-point lead over Claude Code. That sits well within the noise. On top of that, harnesses are often integrated with the benchmark to differing degrees.
Test setup
Three harnesses were tested as shipped:
- Claude Code and OpenCode: specialized file and search tools, long system prompts, automatic compression of the history.
- mini-SWE-agent: just one Bash tool, no context management.
The models were Qwen3.6, Qwen3.8, Deepseek-V4-Flash, GLM-5.3-Flash and HY4-Preview. Claude Opus 5 ran only as a reference in Claude Code. The researchers used the 45 hardest tasks from SWE-bench Verified plus a pool of 447 others; several configurations ran twice to measure the noise.
All runs took place offline. In early tests with web access, 71 percent of attempts by Deepseek and Qwen models fetched the correct fix straight from GitHub, while Claude models almost never did. Those results were discarded. The researchers don't accuse any vendor of training on test data.
Switching harness is like rerolling the dice
On the 447 tasks, Claude Code and mini-SWE-agent (the heaviest and the lightest harness) are less than two points apart for both models tested. Within five points, they count as statistically equivalent.
On the 45 hard tasks, where the researchers had expected the biggest effect, the harnesses are separated by two to five tasks per model; a mere rerun shifts the result by up to three. Sometimes mini-SWE-agent leads, sometimes Claude Code.
| Comparison | Median share of tasks whose outcome flipped |
|---|---|
| two reruns | 13% |
| two harnesses | 13% |
| two models | 22% |
The authors say the harness gap behaves like "a fresh draw from the same noise." Small samples also limit how much you can conclude: with 45 tasks, even a 13-point gap is detected only half the time, while with 447 tasks you can reliably resolve about five points. Zhipu's 2.4 points fall below both thresholds.
OpenCode falls behind
The only measurable harness effect is a consistent deficit for OpenCode of up to nine points on the large pool. About half of it traces back to an output limit: if the model exceeds the limit mid-step while reasoning, Claude Code prompts it to continue, whereas OpenCode ends the step, and the attempt usually fails. A continuation prompt modeled on Claude Code didn't help, because the runaway reasoning rarely recurs on reruns. The rest remains unexplained; the only observation is that models stop working noticeably earlier under OpenCode. OpenCode also had a much tighter time limit on locally hosted models, an uncontrolled factor. Without context management, mini-SWE-agent runs into the context window, mainly on tasks the others fail to solve too. OpenCode's search tools download a binary on first use and fail offline.
The system prompt drives the bill
With the same model, the same tasks and the same price list, one task costs up to three times as much depending on the harness. Tool outputs hardly explain it. What matters is the system prompt and tool descriptions, which are resent at every step:
| Harness | Size (tokens) |
|---|---|
| Claude Code | approx. 16,600 |
| OpenCode | approx. 7,000 |
| mini-SWE-agent | under 1,000 |
According to the researchers' reconstruction, Claude Code also keeps the model's reasoning in the history. After that, context grows at a similar rate in all harnesses. Prompt size sets the base cost, and the number of steps multiplies it. With GLM-5.3-Flash, Claude Code costs almost twice as much as mini-SWE-agent; with Deepseek-V4-Flash, mini-SWE-agent needs so many extra steps that the two come out even. Cheaper cached tokens dampen the differences but barely change the ranking.
No home advantage, open questions on thinking
Deepseek's own harness does no better with its own model, yet costs the most. Claude Opus 5 delivered identical results even after tools were removed from Claude Code. A version a year old solves a similar number of tasks for less than half the cost, because extended thinking wasn't on by default back then.
Thinking produced the only interaction effect: without thinking, mini-SWE-agent loses eleven points with Qwen3.6, while Claude Code and OpenCode stay within the noise. HY4-Preview also loses eleven points in Claude Code without thinking. The authors offer no explanation; they say the test grid is too small.
Our take
The study urges caution with marketing numbers for harnesses: without repeat runs, small leads can't be told apart from chance. The authors recommend publishing a rerun of the same configuration with every harness comparison. A harness buys "fewer ways to lose a task, and a bill, not a success rate." Caveats: the study rests mainly on one benchmark (a small cross-check on Terminal-Bench 2.1 shows the same picture), the closed frontier model ran in only one harness, and the OpenCode deficit is partly unexplained. This is a preprint; data and scripts are on GitHub. In a similar vein, other research has shown that a simple Markdown file beat a complex skill system and that the choice of framework can nearly triple costs.
Sources
- The Decoder (EN) the-decoder.com
- The Decoder (DE) the-decoder.de
- AI Times (KR) aitimes.com
Ask the AI assistant
Questions about this article, installation or background? Our assistant knows this page and runs on our own machine, not in someone else's cloud.
The Assistant is an AI (Gemma 4) and can make mistakes – please check important details against the source. Questions are used only to generate an answer and are deleted after one hour. Please don't enter any personal data.
Comments
What do you think? Already tried it? Write it here, no sign-up needed.
Comments are public. Links aren't allowed, and we delete abusive posts. You can delete your own comment at any time in this browser. Learn more in the Privacy Policy.