
Solo developer releases local world model that turns any image into a playable video
A developer from the r/LocalLLaMA community has published a self-trained world model on Hugging Face. It turns a single still image into an interactive video you control in real time, and it's supposed to run on an RTX 3060 or 4060.
What it's about
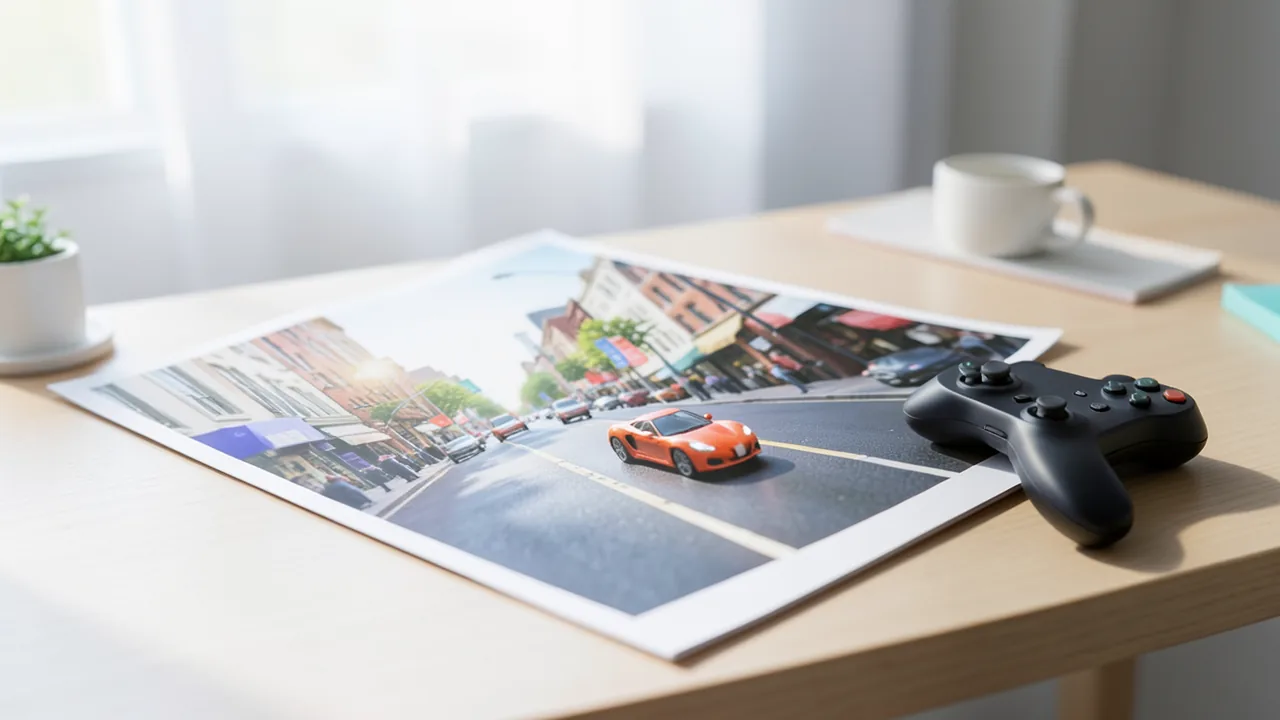
On the Reddit forum r/LocalLLaMA, a developer has presented the first AI model they've ever released publicly: a so-called world model. That's an AI that doesn't just spit out a finished video. Instead, it calculates frame by frame how a scene changes in response to your input, a bit like a video game, just without a programmed game world. You give it any image, and the model turns it into an interactive video you control in real time.
The weights are freely available on Hugging Face at huggingface.co/lucidml/gta. The name points to the GTA game series. The developer says the GTA variant is "more stable than the general model" but can still turn any image into an interactive video. If you don't want to install anything, there's a browser demo: lucidml.ai/dashboard/minidemo?world=gta5. The developer calls it a "simple, fun drifting site."
What a world model is and why it matters
World models are one of the hot research topics in AI right now. A regular video generator takes a text prompt or an image and renders a few seconds of video. Once the clip is done, you have no further say. A world model works in a loop: it looks at the current frame and your controls, such as steering or hitting the gas, and predicts the next frame. It repeats this many times per second. The result feels like a playable world, even though there's no game engine, no 3D models and no physics simulation. The neural network "dreams" all of it.
Until now, systems like this have mostly come from large research labs and usually run on expensive data center GPUs. What's new here is the claim that this model runs locally on ordinary gaming graphics cards.
The tech: a transformer with learned summaries
The post gives only brief details on the architecture. It's a transformer, the same type of network behind language models like ChatGPT. What sets it apart, according to the developer, are "learned summaries." In other words, the model doesn't remember every previous frame in full. It compresses the past into a compact form it learned during training, roughly the way you remember a route after a drive rather than every single frame of it. For real-time models, that's crucial: without a summary, memory use grows with every frame and the model keeps getting slower.
The developer has published details in technical reports at lucidml.ai/summaryformer, where the architecture is apparently called "Summaryformer." The Reddit post doesn't say how big the model is, what data it was trained on or what license it uses.
Hardware and demo
According to the developer, the model runs on an RTX 3060, an RTX 4060 and anything above that. These are popular mid-range cards with 12 GB and 8 GB of VRAM (video memory), respectively. The online demo uses rented GPUs from cloud provider Vast.ai, specifically the RTX 3070, 3080, 4080 and some 50-series cards. The frame rate there is "hard capped." That's why, the developer says, most 50-series cards are "wasted," since they could deliver far more than the demo asks of them. That suggests the model is lean enough for consumer hardware. There are no independent measurements of frame rate or memory use yet.
What you need to try it
- Graphics card: an Nvidia GPU, RTX 3060 (12 GB) or RTX 4060 (8 GB) and up. Around 8 GB of VRAM is likely the minimum. There's no information on AMD cards, Apple Silicon or CPU-only operation. Realistically, a CPU is too slow for real time.
- RAM and storage: not specified. Budget a few GB for the model files and a standard Python setup.
- No hardware of your own? The browser demo runs in the cloud, so there's nothing to install.
- Instructions: How to run the model locally is explained on the Hugging Face page. The Reddit post itself doesn't include installation steps.
Limitations the developer admits
The developer presents the project candidly and without big promises. It's the first model they've ever released, which they say is "a bit scary." They acknowledge there are still plenty of limitations, especially with consistency and image quality. Consistency here means: does the world stay the same if you turn around and look back? That's a well-known problem with world models. Objects vanish, roads change, and after a while the image turns to mush. The developer plans to keep training the model to fix these issues.
The bigger picture
A world model built by a single person, freely downloadable and running on a mid-range graphics card, is unusual in this research field. The well-known systems from big labs are often not public at all or need far more compute. For tinkerers, game developers and researchers, the project is a cheap way to try out and understand the "game without an engine" idea for themselves.
Still, a lot remains unclear. There's no information on model size, license, training data or benchmarks. GTA-style visuals also raise the question of whether the model was trained on footage from a copyrighted game. The post doesn't address that. All performance claims come from the developer alone. Realistically, the model is more an exciting experiment and tech demo than a finished tool. That's exactly what makes it interesting if you want to understand where interactive AI video is heading.
Sources
- Reddit r/LocalLLaMA reddit.com
Try it yourself: lucidml GTA World Model
Explained step by step, no prior knowledge needed – on your own computer or free in your browser.
What can I do with it?
The model takes a still image and turns it into an interactive video you control in real time, similar to a simple racing game. The AI generates every new frame itself, with no game engine or 3D models. According to the developer, the GTA variant works best and is more stable than the general model. In principle, though, any image should work as a starting point. The architecture is a transformer with learned summaries, lean enough for mid-range GPUs. Its limits are consistency, since the world shifts over time, and image quality. It can't compete with commercial games or large video models. Think of it as an exciting experiment.
Who is it worth it for?
Worth it for tinkerers, game developers, AI enthusiasts and researchers with an Nvidia card from the RTX 3060 or 4060 upward who want to experience world models firsthand. If you're expecting a finished game or high-quality video, you'll be disappointed, so try the online demo first.
Ideas: What you can do with it
Upload a photo of a street or landscape and drive around in it. You'll see how the AI imagines the world beyond the edges of the photo. It's a real wow moment and a great way to show the tech to others.
Game developers can use a concept image to quickly get a sense of how a scene feels in motion. It won't replace an engine, but within minutes you get a rough feel for atmosphere and perspective.
Students and AI enthusiasts can watch on their own machine where models like this break down, for example with consistency and object permanence. Paired with the technical reports, it makes a hands-on learning project.
Screen-record your drive through an AI-generated world and cut it into short, surreal clips. The glitches and distortions often have a charm of their own.
Test how smoothly the model runs on your card and compare the frame rate with the online demo. It gives you a feel for how much your hardware can handle for real-time AI.
What your computer needs
The source mentions only one released variant: lucidml/gta. According to the developer, it's the most stable. There's no information on sizes or quantizations. The standard version should run on an RTX 3060 or 4060.
- According to the developer, the model runs on the RTX 3060, RTX 4060 and anything more powerful. Expect about 8 GB of VRAM as a minimum.
- The source says nothing about AMD GPUs, Apple Silicon or CPU-only operation. A CPU is hardly suitable for real time.
- The online demo runs on rented RTX 3070, 3080, 4080 and 50-series cards from Vast.ai, with a capped frame rate.
- Faster cards can deliver more frames per second than the demo uses.
How do I find out what my computer has?
- Windows: Press Ctrl + Shift + Esc → Task Manager → Performance tab → click GPU on the left. At the bottom you'll see Dedicated GPU memory (that's your VRAM). You'll find system memory under Memory.
- Mac: Apple menu at the top left → About This Mac. You'll see your chip (e.g. M2) and memory (e.g. 16 GB). On Apple chips, graphics and processor share this memory.
- Linux: Type
nvidia-smiin the terminal (shows your graphics card and its memory) andfree -hfor system memory.
Guide
This model runs with its developers' own program (guandeh17/Self-Forcing on GitHub). The commands below come from the Model Card and the developers' instructions.
Windows 10 / 11
Windows 10 / 11: not officially tested. The source doesn't mention Windows. The server needs FlexAttention and torch.compile, which often cause trouble on Windows. The safer route is WSL2 (Linux running inside Windows) with the Linux instructions, or just use the online demo at lucidml.ai.
- Check the prerequisites. You need an NVIDIA graphics card with an up-to-date driver and Python 3 from python.org. During installation, tick the "Add to PATH" box. Open PowerShell and use these commands to check that your GPU and Python are detected.
nvidia-smi python --version - Create a working folder and environment. You'll create a folder and a virtual environment, an isolated space for this project's packages. If PowerShell throws a script error when activating it, run Set-ExecutionPolicy -Scope CurrentUser RemoteSigned first.
mkdir gta-welt; cd gta-welt python -m venv .venv .venv\Scripts\Activate.ps1 - Install the packages. This installs the packages listed in the Model Card. Heads up: on Windows, pip install torch often installs a version without GPU support. So grab the install command for the CUDA build from the PyTorch website and run it first.
pip install torch numpy fastapi uvicorn pillow av imageio huggingface_hub - Download the model and code. This downloads the repository with weights and code into the gta folder, about 3.4 GB. Then switch into that folder.
hf download lucidml/gta --local-dir gta cd gta - Start the server. The server loads the model, compiles it with torch.compile and runs a short warm-up. The first time takes a while. If it crashes with a triton or compile error, use WSL2.
python summary_server.py - Check that the server is running. Open a second PowerShell window. Type curl.exe instead of curl, because curl is a different command in PowerShell. If you get a JSON response, the server is running.
curl.exe http://localhost:3002/status - Upload a starting image. Save a landscape screenshot from GTA V as start.png in the current folder. Then send it to the server with this command; test is your username.
curl.exe -F "z0_image=@start.png" http://localhost:3002/z0/test - Connect to a session. The video comes through the WebSocket address ws://localhost:3002/ws/test. There's no browser interface included. Your own client has to send key presses as JSON and display the H.264 frames.
- Result. The GTA world model server is running on your machine on port 3002, has accepted your starting image and can stream 384x672 H.264 video over a WebSocket connection that responds to your key presses.
macOS
macOS: not supported. According to the Model Card, the model runs only with CUDA, meaning NVIDIA graphics cards only. So it won't work on a Mac. Use the browser demo at lucidml.ai (minidemo, world=gta5) instead, or rent a cloud machine with an NVIDIA card.
Linux
Linux: supported. The source requires an NVIDIA graphics card with CUDA. It doesn't name a specific operating system, but Linux is the obvious choice. The browser interface for playing isn't included in the package. If you just want to try it out, use the online demo at lucidml.ai (minidemo, world=gta5).
- Check the prerequisites. You need an NVIDIA graphics card with its driver installed and a recent Python 3. The nvidia-smi command shows your GPU and its memory. If no card shows up, the driver is missing. Without an NVIDIA card the model won't run, because according to the developer it only works with CUDA (NVIDIA's compute interface for GPUs).
nvidia-smi python3 --version - Create a working folder and environment. You'll create a folder with a virtual environment inside it, an isolated space for this project's Python packages. Once activated, you'll see (.venv) at the start of your command line.
mkdir gta-welt && cd gta-welt python3 -m venv .venv source .venv/bin/activate - Install the packages. This installs all the packages the Model Card lists as required. torch is PyTorch, the library that does the math on your GPU. huggingface_hub provides the hf download command. It takes a few minutes, since torch is several GB in size.
pip install torch numpy fastapi uvicorn pillow av imageio huggingface_hub - Download the model and code. This command downloads the full repository into the gta folder, including the weights (about 3.4 GB) and all the code. Then switch into that folder.
hf download lucidml/gta --local-dir gta cd gta - Start the server. Now start the server. It loads the weights, compiles the model for your GPU (torch.compile) and plays a short warm-up session. That's why the first start takes a while. Leave the window open. The server listens on port 3002.
python summary_server.py - Check that the server is running. Open a second terminal. This command asks the server whether it's busy. If you get a JSON response, everything's working. Each process serves only one player at a time.
curl http://localhost:3002/status - Upload a starting image. The model needs a starting image from which it generates the world. Ideally, use a landscape screenshot from GTA V and save it as start.png. This command sends the image to the server; test is your username.
curl -F "z0_image=@start.png" http://localhost:3002/z0/test - Connect to a session and play. The video comes through a WebSocket connection at ws://localhost:3002/ws/test, a persistent connection between your program and the server. The package doesn't include a browser interface. So you need your own small client that sends the pressed keys as JSON, for example {"type": "keys", "pressed": {"w": true, ...}}, and displays the H.264 frames. A session ends after 180 seconds.
- Result. The GTA world model server is running on your machine on port 3002, has accepted your starting image and can stream 384x672 H.264 video over a WebSocket connection that responds to your key presses.
What to do after your first result
- Try different starting images, such as a city, desert or highway. The starting image stays in the model's memory for the whole session and shapes the scene.
- At the top of summary_server.py you'll find the CONFIG dictionary with all settings. Use ws_session_limit_s to change the per-session time limit (default 180 seconds, 0 disables it).
- You can steer with w, a, s, d, shift, space, plus left and right. Your client sends them as a JSON message of type keys.
- If you install flash_attn, a second attention kernel becomes available. It's optional; by default the server uses FlexAttention.
Try it
Use a photo of a city street from the driver's perspective as the starting image and hit the roadTake a screenshot from an open-world game as the starting image and drift around in itUpload your own vacation photo of a coastal road and test how long the world stays stableUse a painting or drawing as the starting image and see how the model carries the style forwardPick a night scene with neon lights as the starting image and check consistency when you turn aroundTips for better results
- Try the online demo first to see what to expect before installing locally.
- Choose starting images that match the training style, such as game-style street scenes from the driver's perspective. That keeps results most stable.
- Keep sessions short, and restart with a new starting image when artifacts appear.
- Read the technical reports at lucidml.ai/summaryformer to understand the architecture and its limits.
If something goes wrong
The post doesn't mention a license or terms of use. Check the Hugging Face page before you reuse the model.
The Reddit post has no setup guide. Follow the instructions in the lucidml/gta repo.
The world changes over time, a known weakness. Long sessions get blurrier or stop making sense.
According to the developer, the general model is less stable than the GTA variant, so start with lucidml/gta.
If you don't have a suitable Nvidia card, use the browser demo instead of wrestling with a local install.
“out of memory,” a crash, or your computer freezes
The model is too big for your VRAM (video memory). Pick a smaller variant from the table above and close other programs, especially games and browsers with lots of tabs.
It runs, but extremely slowly
Your CPU is probably doing the work instead of your graphics card. In Ollama, the PROCESSOR column of ollama ps shows how much runs on the GPU. If it says "100% CPU", update your graphics driver or pick a smaller variant that fits entirely into VRAM (video memory).
“ollama” or “python” is not found
Close the terminal window and open it again so it recognizes the newly installed program. For Python on Windows: reinstall it and check Add python.exe to PATH.
Windows: "Running scripts is disabled on this system"
Run the script with exactly the command above: powershell -ExecutionPolicy Bypass -File try_windows.ps1. This allows execution for this one time only.
Error message when loading the model (version, "trust_remote_code", unknown architecture)
Brand-new models often need the latest software version. With Ollama: update Ollama. With Python: pip install -U transformers in the activated environment. The Model Card usually lists the exact version.
Tokenstrom generates the scripts and notebook automatically. Please take a quick look before running them – they're plain, readable text. Mind the model's license: apache-2.0.
Ask the AI assistant
Questions about this article, installation or background? Our assistant knows this page and runs on our own machine, not in someone else's cloud.
The Assistant is an AI (Gemma 4) and can make mistakes – please check important details against the source. Questions are used only to generate an answer and are deleted after one hour. Please don't enter any personal data.
Comments
What do you think? Already tried it? Write it here, no sign-up needed.
Comments are public. Links aren't allowed, and we delete abusive posts. You can delete your own comment at any time in this browser. Learn more in the Privacy Policy.